
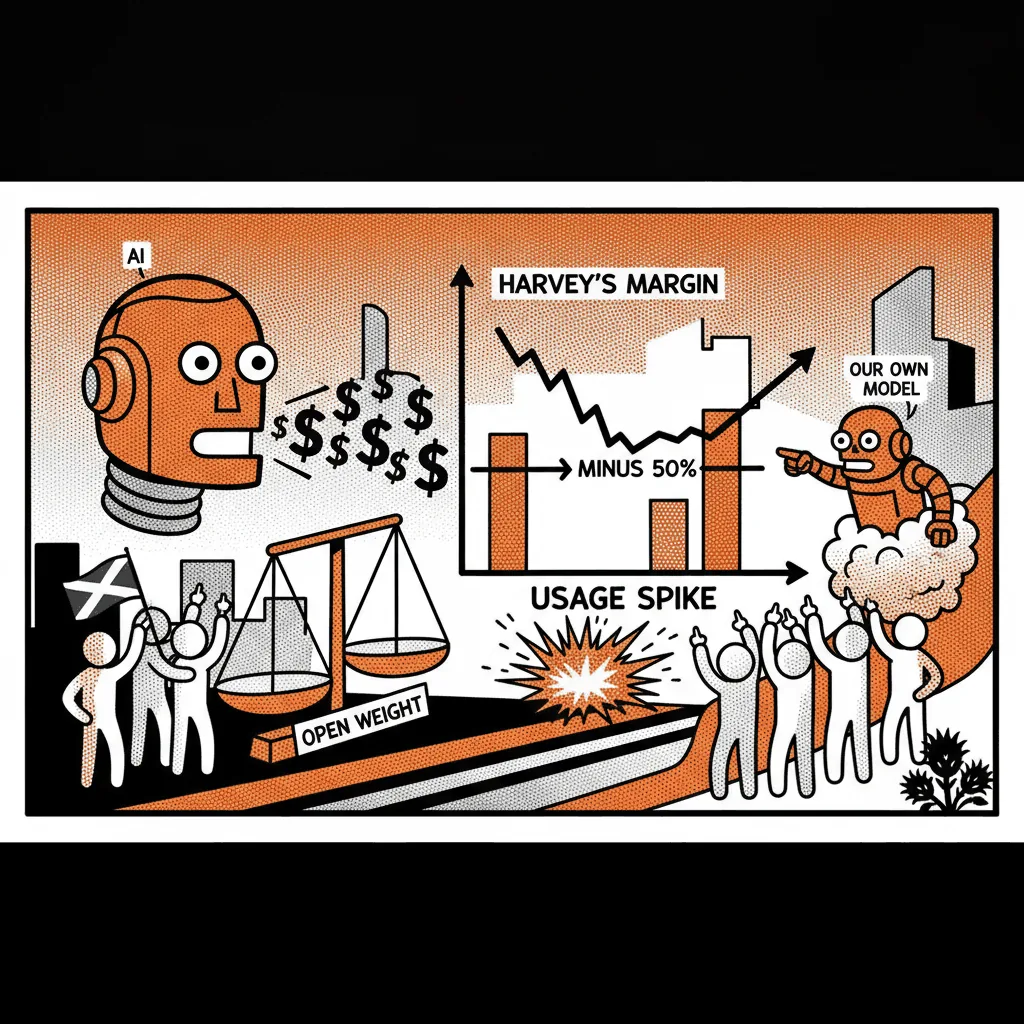
Harvey, the AI legal research platform backed by some of Silicon Valley's sharpest money, had a brutal first half of this year. As reported by The Next Web, its gross margin cratered to minus 50% by June as customer usage of its AI agents scaled faster than its commercial model could handle. The problem was not product-market fit. It was the cost of calling proprietary AI models, OpenAI, Anthropic, Google, at scale. Every query, every agent action, every customer interaction sent another invoice. The margin evaporated in real time.
Harvey is not alone. Abridge, Decagon, Ramp, and Rogo, names backed by Sequoia and other top-tier funds, are all making the same pivot: away from expensive closed API models and towards open-weight alternatives they can run themselves. Harvey rebuilt on Moonshot's Kimi K3, an open-weight model, and its margins turned positive again. That is not a coincidence. That is the economics of AI infrastructure asserting itself, loudly.
Open-weight models, think Meta's Llama series, Mistral, or Falcon from the UAE's Technology Innovation Institute, are freely available for download and can be hosted on your own infrastructure or through specialist cloud providers at a fraction of the per-token cost of proprietary APIs. According to research from a16z's infrastructure team, companies running open-weight models on dedicated compute can cut inference costs by 60 to 80 percent compared with equivalent proprietary API calls at volume. For a business processing thousands of queries a day, that difference is existential.
For Scottish SMEs building AI-powered products or automating internal processes, this trend carries a direct and practical signal. If you are currently routing customer queries, document analysis, or any repetitive AI task through OpenAI's API or Claude and paying per token, your costs will rise as usage rises. That relationship is linear and unforgiving. Scotland's digital economy, supported by Scottish Enterprise's AI investment programmes and the Scottish Government's Digital Strategy, which explicitly targets AI adoption among SMEs, is producing more founders and small teams building AI tools than at any point in recent history. Those teams need to understand unit economics from day one, not after their margins have gone negative.
The practical path is more accessible than most Edinburgh founders realise. Platforms like Hugging Face host thousands of open-weight models with one-click deployment options. Services such as Together AI, Replicate, and Groq allow you to run Llama 3, Mistral, or Qwen at costs measured in fractions of a penny per thousand tokens. For lower-stakes tasks, summarisation, classification, data extraction, first-draft generation, the performance gap between open-weight models and GPT-4 class models has narrowed dramatically through 2024 and 2025. According to benchmarks published by the Stanford Center for Research on Foundation Models, several open-weight models now match or exceed closed models on legal, medical, and coding tasks. The quality is there. The cost is not.
Scotland has a structural advantage here that is rarely discussed. With some of the cheapest renewable electricity in Western Europe and a growing number of colocation facilities in Edinburgh, Glasgow, and Aberdeen, running your own inference on rented GPU servers is increasingly viable for teams that would previously have assumed it was beyond them. Scottish Enterprise's Digital Boost programme offers grant funding for exactly this kind of technical infrastructure work. The tools, the infrastructure, and the support are all present. The only thing missing is the awareness that this is an option at all.